New pysmartdatamodels Version 0.8.2.0: Semantic Identification for Data Spaces

We are happy to announce a new release of our Python package, pysmartdatamodels, version 0.8.2.0. The headline feature is aimed squarely at data spaces: a new function that can give semantic meaning to a payload even when the party who sent it never provided one.
What’s New in This Version?

Semantic identification for data spaces: identify_or_draft_datamodel()

In a data space, you routinely receive payloads from other participants with no guarantee they follow any particular standard. identify_or_draft_datamodel() takes any such payload and does one of two things:

  • If it recognizes the payload as an existing Smart Data Model, it returns that model’s real schema, together with a full validation of the payload against it.
  • If it doesn’t, it drafts a brand new schema.json on the spot — following the same structural conventions as a real Smart Data Model — so you have a ready-to-review starting point instead of nothing at all.

It accepts the payload in any of the three formats actually used in practice — plain key-values, NGSI-v2 normalized, or NGSI-LD normalized — detecting and handling the right one automatically:

from pysmartdatamodels import pysmartdatamodels as sdm

payload = {
    "id": "urn:ngsi-ld:WeatherObserved:station-042",
    "type": "WeatherObserved",
    "temperature": 21.5,
    "relativeHumidity": 0.6
}

result = sdm.identify_or_draft_datamodel(payload)
print(result["schema"]["source"])   # "existing" -- it recognized WeatherObserved
print(result["schema"]["validation"]["result"])  # True

When the payload’s own “type” doesn’t match anything, you can optionally ask it to try a softer, attribute-based match against the whole catalog before giving up and drafting a new schema:

result = sdm.identify_or_draft_datamodel(payload, fuzzy=True, fuzzy_threshold=0.3)

And when nothing matches at all, the drafted schema isn’t just a bare shape guess — any attribute whose name is already established elsewhere in the catalog (over 160,000 attribute definitions) gets its real description, model reference, and units reused automatically, so only genuinely new attributes are left with a plain TODO placeholder.

A real validate_payload()

validate_payload(datamodel, subject, payload) existed before but didn’t actually validate anything. It now runs full JSON Schema validation against the live schema of the data model you name, confirms the payload’s “type” matches, and separately flags – without failing – any attribute that isn’t part of the official definition.

Reliability and performance fixes

  • generate_sql_schema() no longer crashes on attributes that can hold more than one type (e.g. a Property that can also be a Relationship), and no longer generates colliding enum type names when two unrelated models happen to share an attribute name.
  • validate_data_model_schema() no longer terminates your entire Python process on a bad input — it returns an error result like every other function in the package.
  • The ~160,000-entry attribute database is now cached in memory instead of being re-read from disk on every single function call — noticeably faster for any code calling the per-attribute lookup functions in a loop.

Get the Latest Version

Update your installation with:

pip install --upgrade pysmartdatamodels
➔️ Get the package on PyPI

New pysmartdatamodels Version 0.8.1.0: Refreshed Data (reduced size 20 times with same functionality)

We are happy to announce a new release of our Python package, pysmartdatamodels, version 0.8.1.0, with a refreshed attribute database, a smaller download, and a cleanup of some leftover dead code.

What’s New in This Version?

Refreshed Data, End to End

The package’s bundled data — the official list of data models, the attribute metadata, and the full attribute database — had gone stale. Fixing this surfaced two real issues in our own publication pipeline, now resolved:

  • One data model repository had accidentally been left private, which was silently breaking the daily metadata regeneration every time it ran.
  • The database backing the attribute export (see below) was far less complete than it should have been. It’s now fully backfilled: 164,926 attribute records across all 82 subjects.

As always, you don’t need to upgrade the package just to get fresh data — calling update_data() pulls the latest information directly:

from pysmartdatamodels import pysmartdatamodels as sdm
sdm.update_data()

Smaller Install, Compressed Attribute Database

The full attribute database is now shipped gzip-compressed inside the package (~5MB instead of ~110MB) — the installed package footprint drops from over 100MB to under 10MB. This is fully transparent if you use the documented functions (load_all_attributes(), description_attribute(), etc.) — nothing changes in how you call them.

The same compressed file is now also available for direct download, alongside the existing uncompressed one, from the attribute database export page.

Cleanup

Removed a small piece of dead code in generate_sql_schema() left over from an earlier implementation — no change in behavior, just a cleaner function. Thanks to the community member who originally reported it.

Get the Latest Version

Update your installation with:

pip install --upgrade pysmartdatamodels
➡️ Get the package on PyPI

New pysmartdatamodels Version 0.8.0.11: More Reliable SQL Schema Generation

We are happy to announce a new release of our Python package, pysmartdatamodels, version 0.8.0.11, focused on making the SQL schema generation function more robust, fixing how the package exposes its functions, and keeping our GitHub source and published package in sync.

What’s New in This Version?

More Reliable SQL Schema Generation

The generate_sql_schema() function, which turns a data model’s model.yaml into a ready-to-use PostgreSQL CREATE TABLE statement, received three fixes:

  • Column names are now properly quoted, so attribute names that are reserved words or mixed case no longer produce invalid SQL.
  • Properties using anyOf are now supported, in addition to oneOf.
  • The function no longer emits a duplicate id column in the generated schema.

Example:

from pysmartdatamodels import pysmartdatamodels as sdm

sql = sdm.generate_sql_schema("https://raw.githubusercontent.com/smart-data-models/dataModel.Weather/master/WeatherForecast/model.yaml")
print(sql)

More Usable Imports

You can now import the package’s main functions directly from the top level, instead of always going through the submodule:

from pysmartdatamodels import generate_sql_schema, load_all_datamodels

The documented usage pattern below continues to work exactly as before:

from pysmartdatamodels import pysmartdatamodels as sdm

Repository Housekeeping

The source code published on GitHub and the package published on PyPI had drifted apart over the last few releases. With this version, both are back in sync, so what you see in the repository is exactly what you get when you pip install the package.

Get the Latest Version

Update your installation with:

pip install --upgrade pysmartdatamodels
➡️ Get the package on PyPI

Our Commitment to Open and Interoperable Data

We are committed to making data interoperability easier for everyone. Thanks to everyone in the community who reports issues and helps us keep improving pysmartdatamodels!

UNTP Digital Product Passport Joins Smart Data Models: Two new candidate models — DigitalProductPassport and Product

Smart Data Models’ Candidates repository now includes a new candidate standard, untp-v0.8.0, translated from the UN Transparency Protocol (UNTP) Digital Product Passport specification — a B2B data standard, issued as a W3C Verifiable Credential, for carrying product and sustainability information through supply chains. Two entities are covered: DigitalProductPassport and Product.

What’s in it

Model What it is
DigitalProductPassport The W3C Verifiable Credential (VCDM 2.0) envelope: issuer, validity period, credential status, render method, issuing software.
Product The core product data model: identification, classification, material provenance, producing facility, dimensions, packaging, performance claims, and an open industry-specific characteristics extension point.

Every model ships the full set of Candidates artifacts: a JSON Schema, an NGSI-LD @context, and all four example serializations (NGSI-v2 and NGSI-LD, key-values and normalized) — each validated against its own schema.

Two entities, one relationship — not one flattened blob

In the source, DigitalProductPassport.json‘s credentialSubject is literally $ref: "#/$defs/Product" — a 1:1 inline embedding. But Product.json is also published standalone, with its own complete identity independent of any credential wrapper. This candidate keeps that distinction: DigitalProductPassport carries only the envelope fields plus a product Relationship, and Product is its own separately-addressable entity — avoiding a ~20-property duplication and matching how the source itself chose to publish two files, not one.

The VC envelope fields (issuer DID, credential status, render method, issuing software) are modeled faithfully as real typed properties rather than simplified away — even though they’re strictly artifacts of the credential-verification layer, not “product data” per se.

Real context, real examples — not invented

Two things set this translation apart from working off prose docs alone:

  • A genuine published JSON-LD context. UNTP ships a complete, ~106KB context file using JSON-LD type-scoped contexts. This candidate’s context.jsonld IRIs are extracted from that real file — with two scope-collision bugs caught and hand-corrected along the way (a naive flatten of a type-scoped context can silently grab a same-named term from an unrelated class; here it briefly mapped the envelope’s validFrom to an unrelated ConformityProfile field, and the new product Relationship to an unrelated Digital Traceability Event term, before being fixed).
  • Real sample data. Both example.json files are drawn from UNTP’s own published sample instance — a 75 kWh Li-ion EV battery pack passport, complete with real material provenance (cobalt from DRC, lithium from Chile, nickel from Indonesia, …) and EU Battery Regulation performance claims — not fabricated placeholder values.

One naming fix was needed: the source’s own @context property (the W3C VC context array) would collide with NGSI-LD’s reserved top-level @context mechanism, so it’s renamed to vcContext — the same pattern already used for a dataProvider collision in the Gaia-X candidate.

Note on scope

Per explicit instruction, only these two entities are covered. UNTP defines several other credential types this specification references — Digital Conformity Credential, Digital Facility Record, Digital Traceability Event, Digital Identity Anchor — none of which are modeled here. Fields that reference them (e.g. producedAtFacility, a claim’s evidence links) stay exactly as the source declares them, not promoted to Relationships pointing at not-yet-modeled entity types.

Try it, and tell us what’s missing

This is a Candidate — a first, carefully-sourced translation, not yet promoted to an official Smart Data Models subject. Before that step:

  • License terms haven’t been confirmed against the spec-untp repository’s own LICENSE file yet.
  • Overlap with other Smart Data Models product/traceability vocabularies hasn’t been checked in detail.

Browse the models, open an issue, or send a PR: 👉 https://github.com/smart-data-models/Candidates/tree/master/standards/untp-v0.8.0

Gaia-X Ontology Joins Smart Data Models: 165 Candidate Models for Cloud, Connectivity & Trust

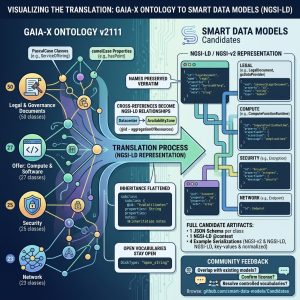
Smart Data Models’ Candidates repository now includes a new candidate standard, gaiax-ontology-v2111, translated from the Gaia-X ontology v2111 — the vocabulary behind Self-Descriptions in Gaia-X federated data spaces and cloud ecosystems. All 165 classes published at docs.gaia-x.eu/ontology/v2111/classes now have an NGSI-LD / NGSI-v2 representation.

What’s in it

Gaia-X’s ontology is broader than a typical device/observation vocabulary — it describes both the physical/technical side of an offering and the legal/governance claims attached to it. That split shows up directly in the model mix:

Category Models Examples
Legal & governance documents 50 LegalDocument, TermsAndConditions, DataUsageAgreement, ServiceAgreementOffer
Compute & software 27 CPU, GPU, Memory, Hypervisor, ComputeFunctionRuntime, Image
Security 25 Encryption, PhysicalSecurity, InformationSecurityPolicies, ProductSecurity
Network 23 Endpoint, VLANConfiguration, InterconnectionServiceOffering, PointOfPresence
Infrastructure 19 Datacenter, AvailabilityZone, Region, PhysicalResource
Service offerings 17 ServiceOffering, ComputeServiceOffering, StorageServiceOffering
QoS metrics 13 Latency, Jitter, PacketLoss, Throughput, IOPS
Storage 13 BlockStorageConfiguration, ReplicationPolicy, SnapshotPolicy
Data products 13 DataProduct, DataProductCatalogue, EvidenceTemplate
Trust framework 10 Ecosystem, EcoTrustScope, EcoTSP, CompliantCredential
+ identifiers, measurement, FaaS, environmental, and more ~19 VatID, EORI, EnergyMix, WaterUsageEffectiveness

Every model ships the full set of Candidates artifacts: a JSON Schema, an NGSI-LD @context, and all four example serializations (NGSI-v2 and NGSI-LD, key-values and normalized) — each validated against its own schema.

Translation notes

  • Names preserved verbatim. Gaia-X’s own class and property names (hasPoint-style camelCase, PascalCase classes) are kept exactly as the ontology defines them — no forced renaming.
  • Cross-references become NGSI-LD Relationships. Any property whose range is another Gaia-X class (e.g. Datacenter.aggregationOfResources → AvailabilityZone) is modeled as a Relationship, not an inlined object, so the resulting graph mirrors the ontology’s own linking structure.
  • Inheritance is flattened, not duplicated in text. A subclass’s schema only lists its own properties; inherited ones are documented on the parent model and referenced by name in the description, matching how the source ontology itself organizes properties.
  • Open vocabularies stay open. A number of Gaia-X properties reference controlled vocabularies (e.g. DiskType, HypervisorType) that aren’t enumerated on the class documentation pages themselves; those are modeled as open strings with a note in the description rather than an invented closed enum.
  • One naming collision, resolved explicitly. DataUsageAgreement‘s own dataProvider property (the participant providing a Data Product) would collide with the Candidates convention’s boilerplate dataProvider metadata field (harmonised-data-entity provider). It’s exposed as gxDataProvider instead, with the substitution documented in the schema’s own description.

Try it, and tell us what’s missing

This is a Candidate — a first, carefully-sourced translation, not yet promoted to an official Smart Data Models subject. A few things are open and would benefit from community input before that step:

  • Overlap with existing Smart Data Models subjects (dataModel.Device, generic infrastructure/building vocabularies) hasn’t been checked in detail.
  • License terms for the specific v2111 release should be confirmed before promotion out of Candidates.
  • A handful of controlled vocabularies referenced by the ontology (e.g. disk/hypervisor/firmware type enumerations) aren’t resolved to closed lists yet — see the individual schema descriptions for which ones.

Browse the models, open an issue, or send a PR: 👉 https://github.com/smart-data-models/Candidates/tree/master/standards/gaiax-ontology-v2111

Introducing the Smart Data Models Candidates Repository

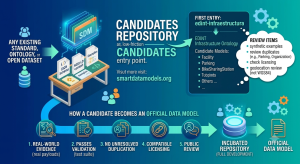
The Smart Data Models now has a Candidates repository — a low-friction entry point where any existing standard, ontology or open dataset can be translated into the SDM shape (JSON Schema + NGSI-LD context + examples) before anyone commits to the full contribution process. The first entry, translated from the EDINT Infrastructure Ontology, is live today — and it needs your help to move forward.

What is the Candidates repository?

Until now, turning an external standard into a Smart Data Model meant going almost straight to the Incubated repository, where a contributor actively develops the model to the point of passing our full validation suite and preparing it for official publication. That’s the right process once someone is committed to doing the work — but it leaves no room for a lighter step: “here is a standard that looks like it maps well onto NGSI-LD — does anyone want to develop this further?”

The Candidates repository fills that gap. It maps existing standards — ontologies, open data schemas, sector vocabularies — into the SDM format (JSON Schema, JSON-LD context, key-value and NGSI-LD normalized examples) as a starting point, organized standard-first:

standards/<standard-slug>/
  standard-metadata.yaml
  models/<EntityName>/
    schema.json
    context.jsonld
    examples/
      example.json
      example-normalized.jsonld

A candidate is not a finished data model. It’s a proposal: a structurally valid, plausible translation that any user of Smart Data Models can pick up, test against real payloads, comment on, correct, or use as the basis for a full contribution to Incubated.

The first example: the EDINT Infrastructure Ontology

The first entry, edint-infraestructura, translates the EDINT Infrastructure Ontology — a formal OWL vocabulary developed under the EU-funded EDINT (Espacio de Datos para las Infraestructuras Urbanas Inteligentes) project for describing a municipality’s public and private facilities: educational, cultural, social and sports centers, health centers, on-street and off-street parking, and shared-bicycle stations, together with the sensors, observations, management roles and organizations involved in operating them.

Eleven candidate models were generated: Facility, Parking, BikeSharingStation, ObservationPoint, AccessSensor, CountingSensor, AccessObservation, CountingObservation, Violation, ManagementRole and Organization. Every schema is valid JSON Schema (Draft 2020-12) and every example validates against its own schema — but that’s where “finished” stops. In the spirit of being upfront about what a Candidate actually is, here’s exactly where this one stands:

  • Real examples exist for only one of the eleven models. Facility is grounded in a real record from the source ontology’s own example data (a municipal day-care center in Madrid). The other ten — the sensors, observations, violations, roles — have plausible but synthetic example payloads, because the source ontology itself doesn’t ship real instance data for them. This is the single most useful thing the community could contribute right now: real payloads from an actual access-control sensor, a real counting observation, a real management-role record.
  • Two models likely duplicate existing official subjects. Parking and Organization are thin, attribute-free specializations in the source ontology and may well overlap with the existing official dataModel.Parking and dataModel.Organization. This needs a real review before either goes any further.
  • The source ontology is licensed CC-BY-SA-4.0 (ShareAlike), while SDM contributions are conventionally CC-BY-4.0. This hasn’t been resolved and is flagged directly in the candidate’s standard-metadata.yaml for whoever picks this up next.
  • Geolocation needs a second look. The source ontology’s geometry is expressed in a projected coordinate system (not WGS84), so the example coordinates here are illustrative Madrid locations, not verified reprojections of the original data.

None of this makes the candidate useless — quite the opposite. It’s exactly the kind of concrete, checkable list that turns “someone should look into this standard” into a set of small, tractable tasks anyone can pick up.

How a Candidate could become an official data model

There is no formal graduation process yet, and we’d rather propose one in the open than invent it quietly. Here’s a first draft, and we’re actively looking for feedback on it:

  1. Real-world evidence. At least one model in the candidate has real, non-synthetic example payloads from an actual system or dataset using it.
  2. Passes validation. The candidate’s schemas and examples pass the standard SDM test suite with zero blocking failures (the same 12 checks used for Incubated contributions).
  3. No unresolved duplication. Any overlap with an existing official model has been explicitly checked and either resolved (extend the existing model instead) or justified (the candidate covers something genuinely different).
  4. Compatible licensing. The source material’s license allows redistribution under the terms Smart Data Models publishes under.
  5. A short public review. A brief comment period on the candidate’s pull request or a linked issue, open to anyone in the community.

Once a candidate clears these, it moves into the normal Incubated workflow for full development ahead of official publication.

How to get involved

  • Browse the repository: github.com/smart-data-models/Candidates
  • Search all candidates: smart-data-models.github.io/Candidates — a searchable, always up to date index of every candidate standard and model
  • Contribute a real example for any of the eleven EDINT models above — open a pull request against standards/edint-infraestructura/, or an issue if you’re not sure how.
  • Propose a new candidate: if you know a standard, ontology or open dataset that should have an SDM mapping, open an issue describing it, or submit the translated standards/<slug>/ folder directly.
  • Give feedback on the promotion criteria above — they’re a first draft, not a final decision.

Find all published Smart Data Models at smartdatamodels.org/ search menu, and everything currently in development in the Incubated repository.

New data models OSMBoundary, OSMClub, OSMCraft, OSMEmergency, OSMGeological, OSMHealthcare, OSMHistoric, OSMIndoor, OSMManMade, OSMMilitary, OSMOffice, OSMPlace, OSMPower, OSMRoute, OSMTelecom, OSMTrafficSign and OSMWater at subject dataModel.OpenStreetMap

We are pleased to announce the publication of OSMBoundary, OSMClub,  OSMCraft,  OSMEmergency,  OSMGeological, OSMHealthcare, OSMHistoric, OSMIndoor, OSMManMade, OSMMilitary, OSMOffice, OSMPlace, OSMPower, OSMRoute, OSMTelecom, OSMTrafficSign and OSMWater within the subject dataModel.OpenStreetMap.

OSMBoundary: Administrative and other boundaries from OpenStreetMap tagged with boundary=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMClub: Social, sports, or interest-based clubs from OpenStreetMap tagged with club=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMCraft: A place for crafts and manual trades from OpenStreetMap tagged with craft=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMEmergency: An emergency facility or equipment from OpenStreetMap tagged with emergency=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMGeological: Geological features from OpenStreetMap tagged with geological=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMHealthcare: Healthcare facilities and services from OpenStreetMap tagged with healthcare=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMHistoric: A historic site or monument from OpenStreetMap tagged with historic=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMIndoor: Indoor features from OpenStreetMap tagged with indoor=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMManMade: An artificial structure from OpenStreetMap tagged with man_made=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMMilitary: Military zones and buildings from OpenStreetMap tagged with military=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMOffice: An office or place of business from OpenStreetMap tagged with office=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMPlace: Geographical places from OpenStreetMap tagged with place=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMPower: Facilities for generation and distribution of electrical power from OpenStreetMap tagged with power=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMRoute: Established routes from OpenStreetMap tagged with route=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMTelecom: Telecommunication infrastructure from OpenStreetMap tagged with telecom=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMTrafficSign: Road and traffic signs from OpenStreetMap tagged with traffic_sign=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMWater: Bodies of water from OpenStreetMap tagged with water=* or natural=water. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

We are grateful to OpenStreetMap contributors from OpenStreetMap (This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.) for their contribution to these data models.

New data models OSMAdvertising and OSMBarrier at subject dataModel.OpenStreetMap

We are pleased to announce the publication of OSMAdvertising and OSMBarrier within the subject dataModel.OpenStreetMap.

OSMAdvertising: Advertising installations from OpenStreetMap tagged with advertising=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

OSMBarrier: Barriers and physical obstructions from OpenStreetMap tagged with barrier=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.

We are grateful to OpenStreetMap contributors None from OpenStreetMap (This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.) for their contribution to these data models.

Find all published Smart Data Models at smartdatamodels.org.

New data model OSMAeroway at subject dataModel.OpenStreetMap

We are pleased to announce the publication of OSMAeroway within the subject dataModel.OpenStreetMap.


We are grateful to OpenStreetMap contributors from OpenStreetMap for their contribution to these data models. (This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.)

OSMAeroway: An aeroway feature from OpenStreetMap tagged with aeroway=*. This data model is a derivative work based on the OpenStreetMap Wiki, licensed under CC BY-SA 2.0 by OpenStreetMap contributors.